
Contrary to common belief, VPS speed issues are more frequently caused by memory and storage limits than processor constraints. Proper diagnosis through targeted testing can lead to more effective upgrades and better server performance.
For most VPS users, poor speed is blamed first on the processor. In practice, that is often the wrong diagnosis. A virtual server’s performance depends on the balance between compute, memory and storage, and the slowest component usually determines how quickly a request completes. That is why the most useful first step is not buying more cores, but identifying where time is being lost.
On a VPS, the processor handles computation, RAM keeps active data in immediate reach, and the disk stores site files, databases and everything else the system must fetch on demand. When one of these resources becomes the bottleneck, the others cannot compensate fully. According to DevOps School, upgrading the wrong component may deliver little or no improvement, which is why measurement matters more than assumption.
CPU is still important, particularly in shared environments where multiple tenants are competing for the same physical machine. VPS Scout notes that the headline number of cores matters less than the quality of the underlying CPU, the provider’s allocation practices and the workload itself. In busy hosting environments, a server may also suffer from “steal time”, when the virtual machine has to wait because the host is serving another customer. If that figure stays elevated, the issue may be the platform rather than the application.
Memory is often the more common constraint. Host Handbook says RAM is frequently the bottleneck for web applications because it allows multiple requests to be handled without resorting to swap. Linux uses spare memory for caching, so a low free-memory reading is not necessarily a problem; what matters is available memory. Once the system begins swapping to disk, responsiveness usually drops sharply, and if swap pressure continues, the operating system may terminate the largest process to recover stability.
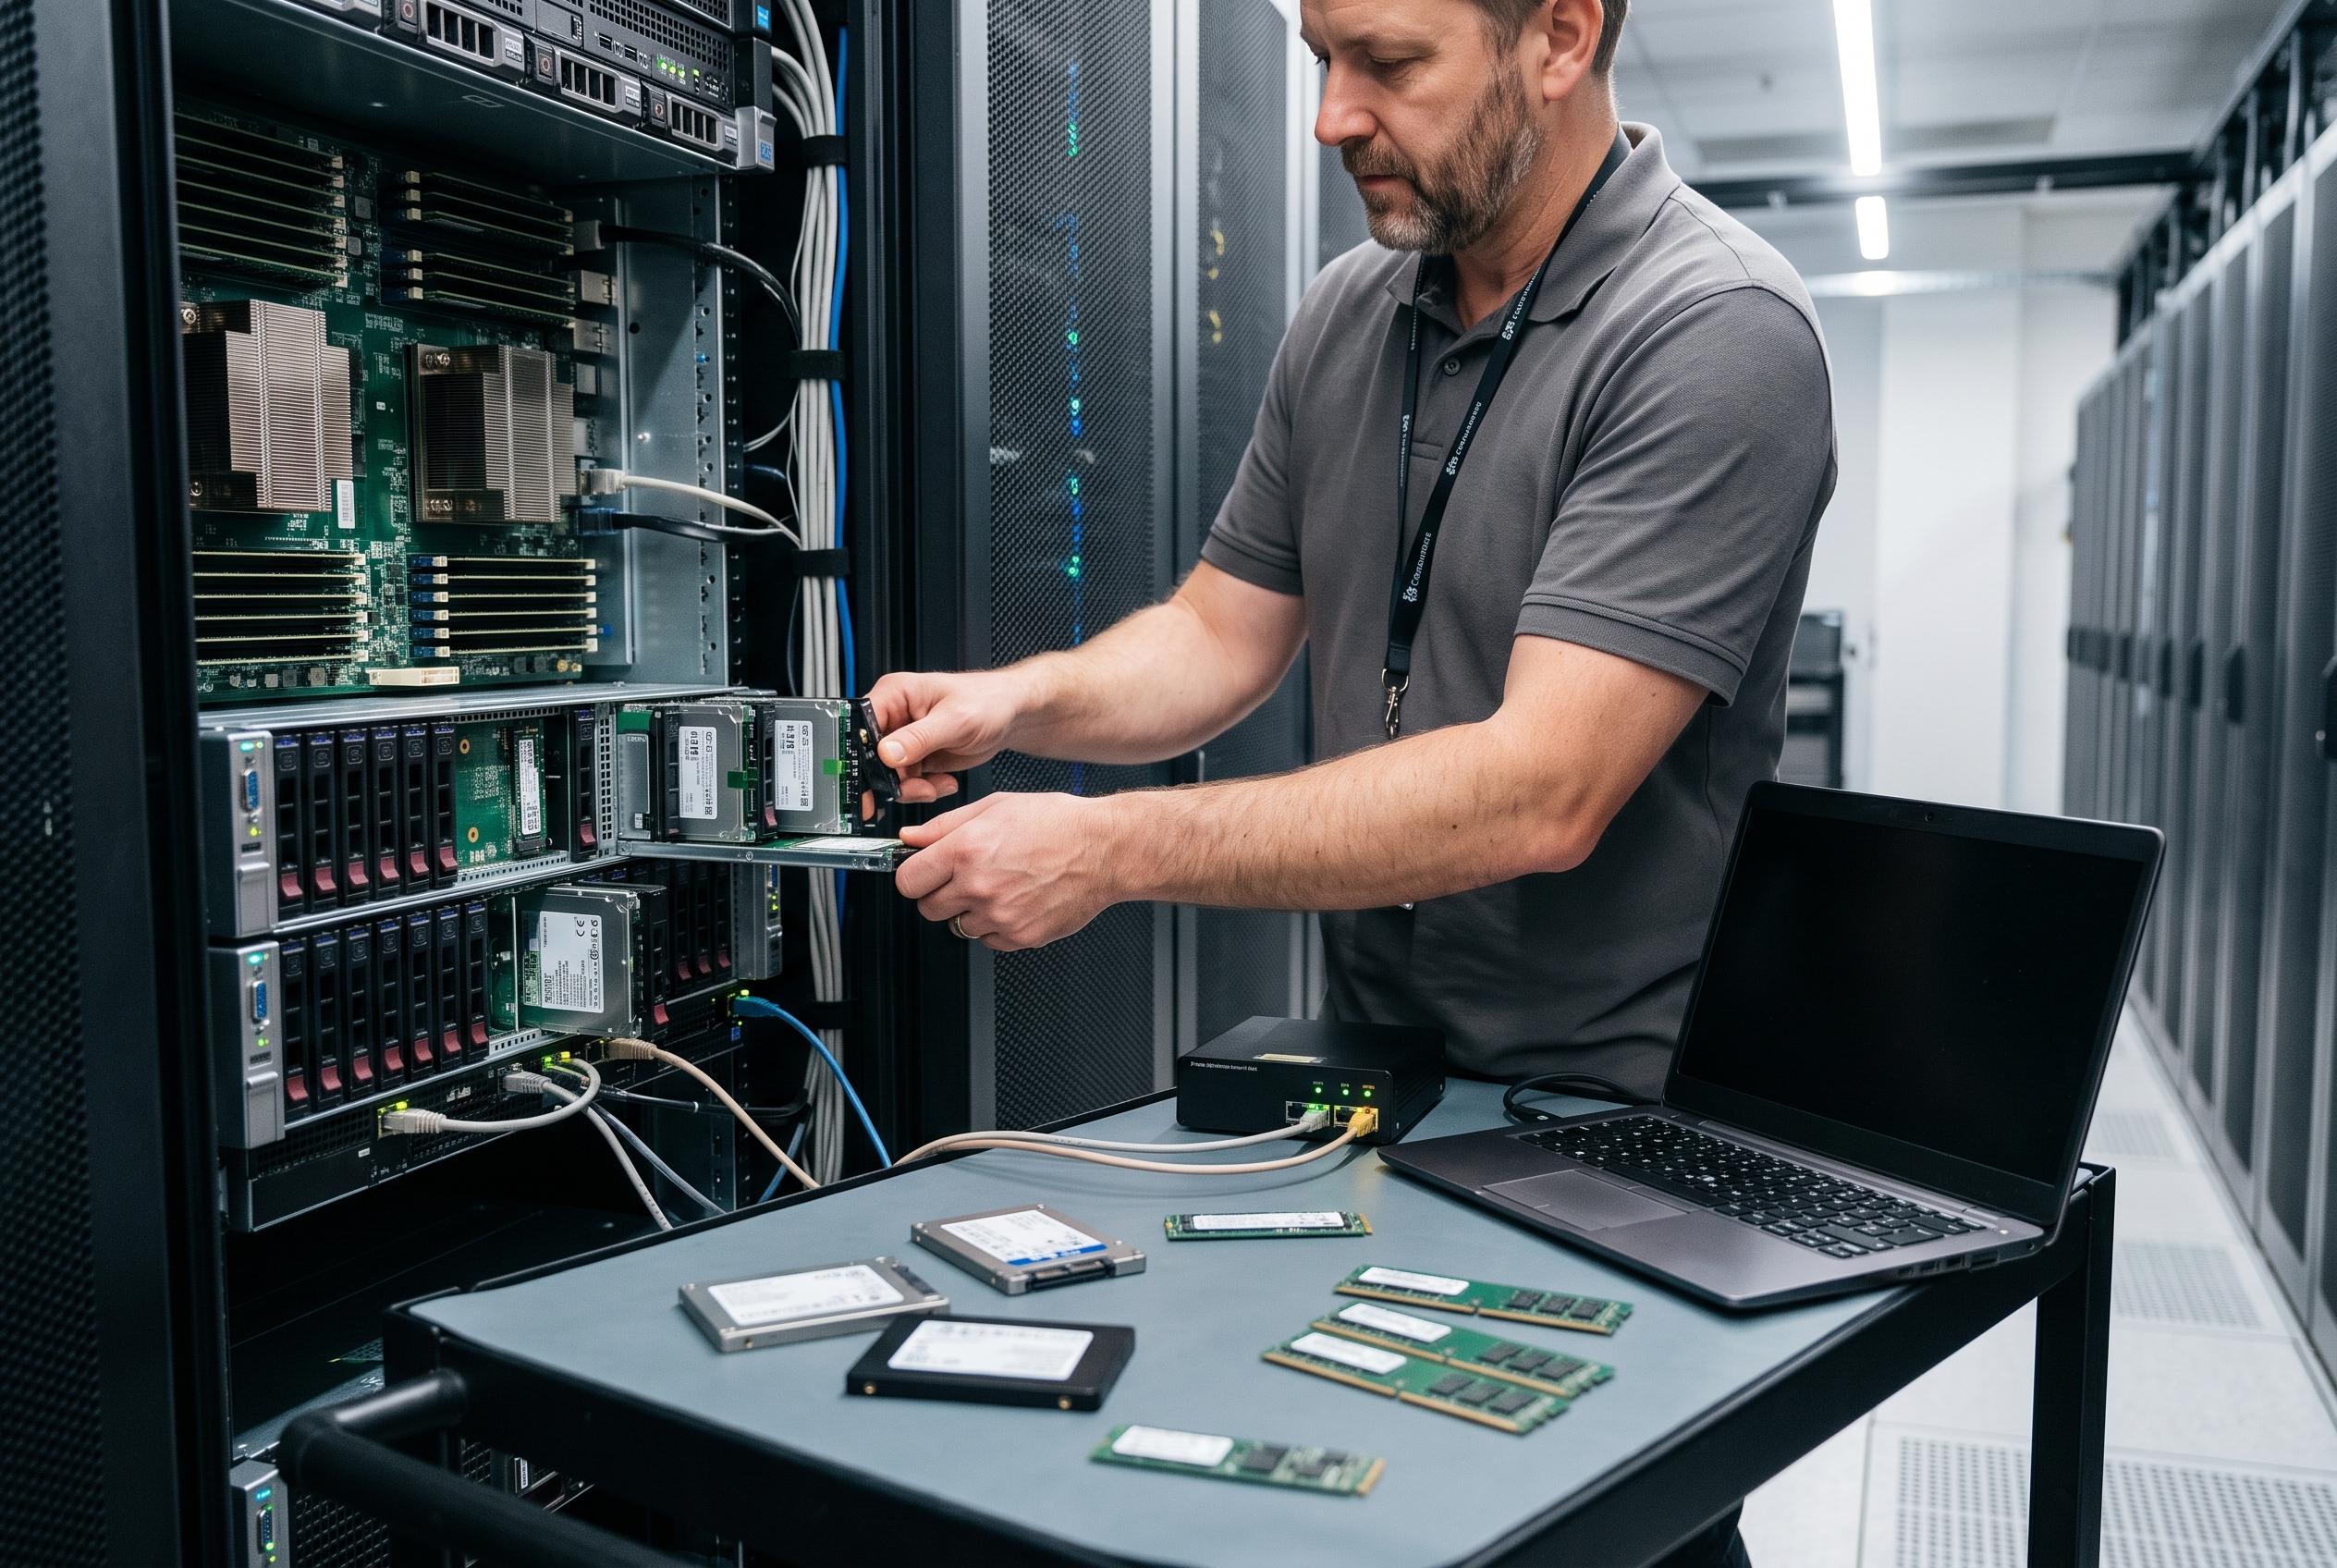
Storage can also have a major effect, especially on sites that rely heavily on databases, file access or background tasks. DevOps School distinguishes between hard drives, SATA SSDs and NVMe storage, with the latter offering much lower latency and higher throughput. That makes NVMe particularly suitable for ecommerce platforms, content-heavy sites and mail servers, where many small reads and writes can quickly expose slower disks. The choice of storage is therefore not just about capacity, but about how quickly the server can serve repeated requests.
The practical way to diagnose the problem is to test, not guess. DevOps School recommends checking the output of top for disk wait time and steal time, using free -h to assess memory pressure and swap usage, and running iostat -x 1 to see how long disk operations spend in queue. Changing one resource at a time makes the effect clearer. For many small sites, the best order of upgrades is often RAM first, then storage, and only then the processor, unless the measurements point elsewhere. Caching at the application level remains a low-cost way to reduce pressure across all three resources.
Disclaimer: This content is intended for informational purposes only. Readers are advised to exercise their own judgement, conduct due diligence, or consult a qualified expert before acting on any information provided.